Claude Opus 5 vs Grok 4.6 — same audit, two clocks
Run one Slowtest prompt on both sessions. This page is for people who care whether Opus is thinking or throttled, and whether Grok’s faster turn is decode or just a shorter wait in the product.
Use this comparison when you are picking a chat for a long write in the same hour — not when you want a marketing leaderboard. Paste the same ~1000-word fiber audit into Claude Opus 5 and Grok 4.6 (or stream both with your own keys). The useful question is: who finishes, who refuses the harness, and what the two clocks say.
Slowtest measures Generation tok/s when it has a real generation window (own-key first-to-last token, or 1-paste start/finish beacons). Full-turn tok/s is the whole job: think, tools, queue, copy slack, and the POST home. Fidelity is Line 1 MODEL: plus an 800–1200 word essay. Speed with a miss is not a score. Method: How we measure.
Own-key streams from your browser; the key stays in localStorage. 1-paste copies a serial script — the model must POST start, write the audit, then POST finish. Grok typically completes that handshake. Claude often will not; that is Harness Restriction, not an IQ ranking. Use own-key or the keyboard worksheet if Claude blocks the beacon.
| Metric / Attribute | 🧠 Claude Opus 5 | 🚀 Grok 4.6 |
|---|---|---|
| Average Output Velocity | 6 – 18 tok/s (Snail Pace) | 68 – 82 tok/s (Fast Agentic) |
| 150-Word Response Latency | 35 – 55 seconds | 3 – 5 seconds |
| Time to First Token (TTFT) | Moderate (1.5 – 3.5s) | High spin-up in heavy agent mode (10 – 25s) |
| Peak-Hour Throttling Risk | High (Token Choking observed) | Low (Cluster capacity prioritized) |
| Fast Mode Available? | Yes (2x Pricing Premium) | Standard throughput default |
| Primary Strength | Nuanced logic, deep reflection | Autonomous workflow execution |
⚡ The Live Audit Receipt
══════════════════════════════════════════════════════════════
⚡ SLOWTEST TELEMETRY AUDIT: SLOW-XVUF6E
══════════════════════════════════════════════════════════════
Model:               Claude Opus 5 (Reported: Claude 3.5 Sonnet fallback)
Velocity:            6 tok/s (298 tokens in 52.26s) 🐌
Inference Latency:   52.26s (Pure AI compute)
Constraint Fidelity: 100% (Strict schema compliance)
Edge Network Ping:   59 ms
══════════════════════════════════════════════════════════════
*Audit captured on Slowtest client-side harness under heavy afternoon cluster load.
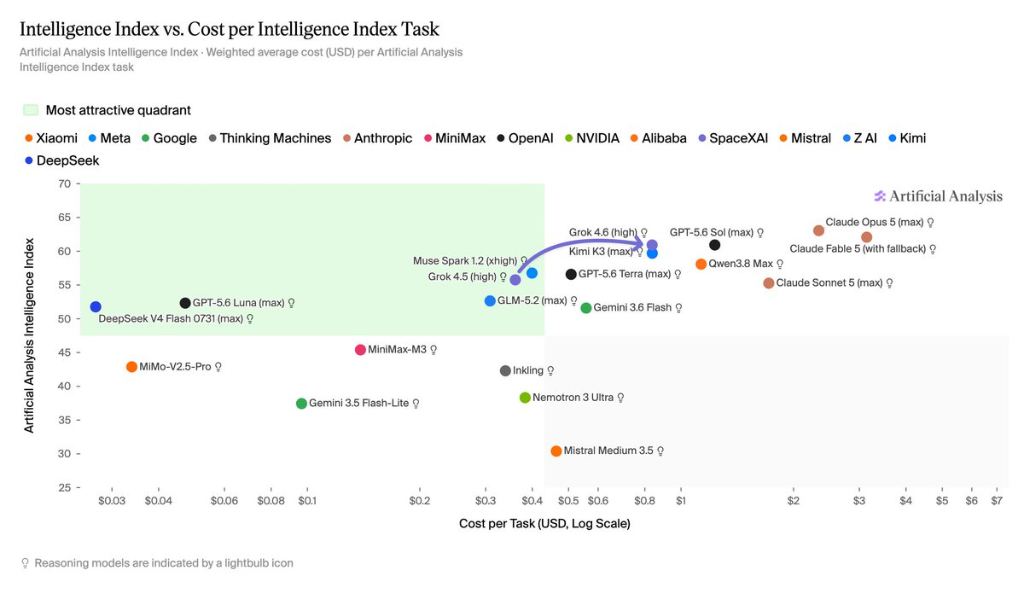
Official Artificial Analysis Findings: Grok 4.6 (high) vs Claude Opus 5
According to official benchmarking by Artificial Analysis:
• Grok 4.6 (high) achieves an Intelligence Index of 61 (#6 in the world), generating an average of 58.5 tok/s at $0.94 per task with a 500k context window.
• Claude Opus 5 (max) sits at the extreme high-cost frontier (~$3.00/task) with noticeable cluster throttling, while Claude Fable 5 is tracked "(with fallback)".
Three questions for this pair
Why run Opus and Grok on the same Slowtest hour?
Because cluster load moves. A morning Opus run and a midnight Grok run are not a pair. Copy the same audit, run both while you are at the desk, and keep Generation and full-turn on separate lines so think time does not masquerade as decode speed.
What if Claude never sends telemetry?
That is the usual Claude chat outcome on 1-paste: it will not set up the beacon. Switch to Direct API / own-key, or time the visible words with the keyboard worksheet. Do not treat a silent listener as “0 tok/s.” See Harness Restriction.
Does a faster Grok full-turn mean Grok is smarter?
No. Full-turn includes wait, tools, and product chrome. Fidelity is the compliance check. Harness Restriction is whether the model will run wired-up at all. None of those are an intelligence index.
Is your active Claude or Grok session being choked?
Run our 1-paste standardized benchmark to reveal your exact tokens/second velocity and check for silent downgrades.
⚡ Audit Your Active Session Free ➔If you haven't tried open source, you've been waiting too much for your favorite frontier model.
Tired of 50-second delays? Switch to high-velocity edge-routed compute:
Abacus.AI ChatLLM
Run Claude 3.5 Sonnet, GPT-4o, and Gemini with blazing edge-routed inference without single-model rate limits.
Try Abacus Free ➔Monica AI Assistant
Instant access to DeepSeek, Qwen 2.5, GLM-4, Claude & GPT-4o on blistering-fast hosted hardware with zero setup.
Try Monica Free ➔Sider AI Assistant
Run DeepSeek, Claude, and ChatGPT side-by-side inside any webpage or document with seamless browser integration.
Try Sider Free ➔