GPT-5.6 vs DeepSeek V4 — closed API vs hosted open weights
Same Slowtest audit. Different sockets. Use this when you need to see whether your GPT-5.6 key is waiting in line while a hosted DeepSeek box is already streaming — not to declare a winner on intelligence.
Reach for this pair when the decision is “pay the official API” vs “run open weights on someone else’s GPUs.” Label the host. A DeepSeek run on a scorching host is not the same clock as DeepSeek on a laptop, and a GPT-5.6 run at 3am is not the same as peak TPM throttle.
Slowtest still only claims what it can clock: Generation tok/s from a real generation window, full-turn tok/s for the whole job, and fidelity (Line 1 MODEL:, 800–1200 words). The comparison table on this page is industry context. It is not the Insights TPS ledger. Empty ledger cells stay empty until someone pastes a Slowtest receipt. Method: How we measure.
Own-key: OpenAI-compatible stream from the home page (custom endpoint if your DeepSeek host speaks that dialect). 1-paste: works when that chat or agent will POST start and finish. ChatGPT consumer chat often will not; a coding agent sometimes will. See Harness Restriction — willingness to run wired-up, not a quality score.
| Metric / Attribute | 🌐 OpenAI GPT-5.6 | 🚀 DeepSeek V4 |
|---|---|---|
| Standard API Throughput | 45 – 70 tok/s | 90 – 140+ tok/s (Hosted) |
| P95 Latency Spikes | 8 – 15s (Traffic contention) | Consistent (< 2s) |
| Cost per 1M Output Tokens | $15.00 – $30.00 | $0.28 – $0.95 (Fractional) |
| Deployment Freedom | Locked to OpenAI API & Azure | Any Cloud, On-Prem, or Local |
| Rate Limit Risk | Severe TPM / RPM throttling | Unlimited on dedicated compute |
| Best Use Case | Enterprise legacy compliance | High-throughput agentic automation |
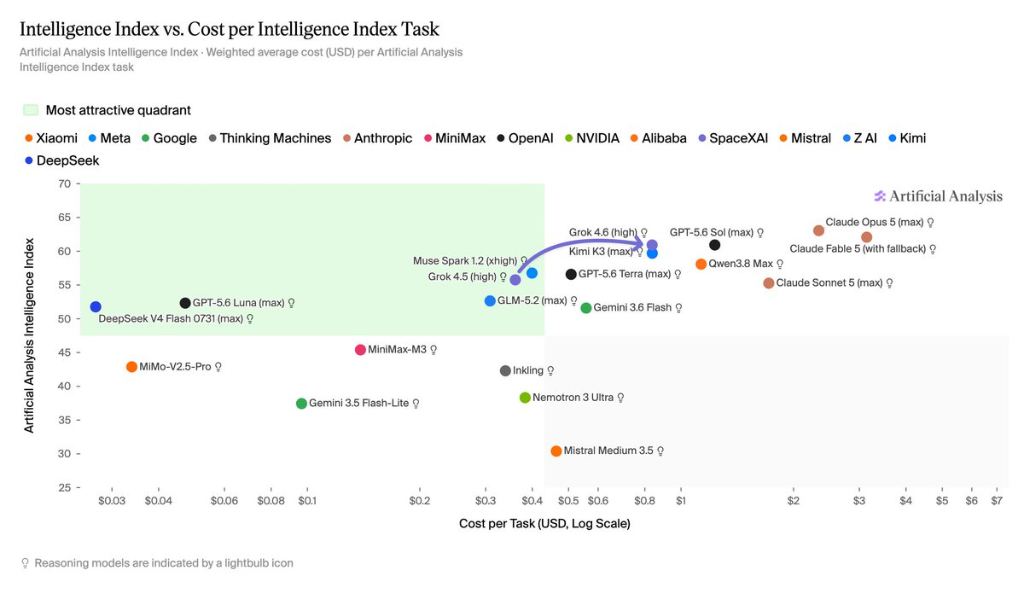
DeepSeek V4 Dominates the "Most Attractive" Efficiency Quadrant
Independent tracking by Artificial Analysis demonstrates the staggering compute gap: DeepSeek V4 Flash sits squarely in the green "Most Attractive Quadrant" at roughly ~$0.025 per task, while GPT-5.6 Sol ($1.10/task) charges a massive proprietary premium for comparable downstream performance.
Three questions for this pair
When does hosted DeepSeek beat GPT-5.6 on this test?
When the OpenAI socket is queued or TPM-capped and the DeepSeek host is not. That is infrastructure, not a proof that V4 “wins” reasoning. Write down the host. Compare Generation to Generation, not a vendor chart to a Slowtest receipt.
Own-key or 1-paste for this pair?
Own-key if you have an OpenAI key or an OpenAI-compatible DeepSeek URL — that is the clean first-to-last Generation clock. 1-paste if you are in a chat that will POST beacons. ChatGPT’s consumer box often will not; then use the keyboard worksheet.
Are the tok/s figures in the table Slowtest measurements?
No. They are context on this landing page. The curated Slowtest ledger lives on Insights and is blank until a real run is entered. Do not invent a number to fill a cell.
Test your active session against these benchmarks
Run Slowtest's 1-paste standardized benchmark to reveal your exact tokens/second velocity and check for silent downgrades.
⚡ Audit Your Active Session Free ➔If you haven't tried open source, you've been waiting too much for your favorite frontier model.
Tired of closed-tier latency? Run open weights on scorching fast hosted hardware:
Abacus.AI ChatLLM
Run Claude 3.5 Sonnet, GPT-4o, and Gemini with blazing edge-routed inference without single-model rate limits.
Try Abacus Free ➔Monica AI Assistant
Instant access to DeepSeek, Qwen 2.5, GLM-4, Claude & GPT-4o on blistering-fast hosted hardware with zero setup.
Try Monica Free ➔Sider AI Assistant
Run DeepSeek, Claude, and ChatGPT side-by-side inside any webpage or document with seamless browser integration.
Try Sider Free ➔